Admin
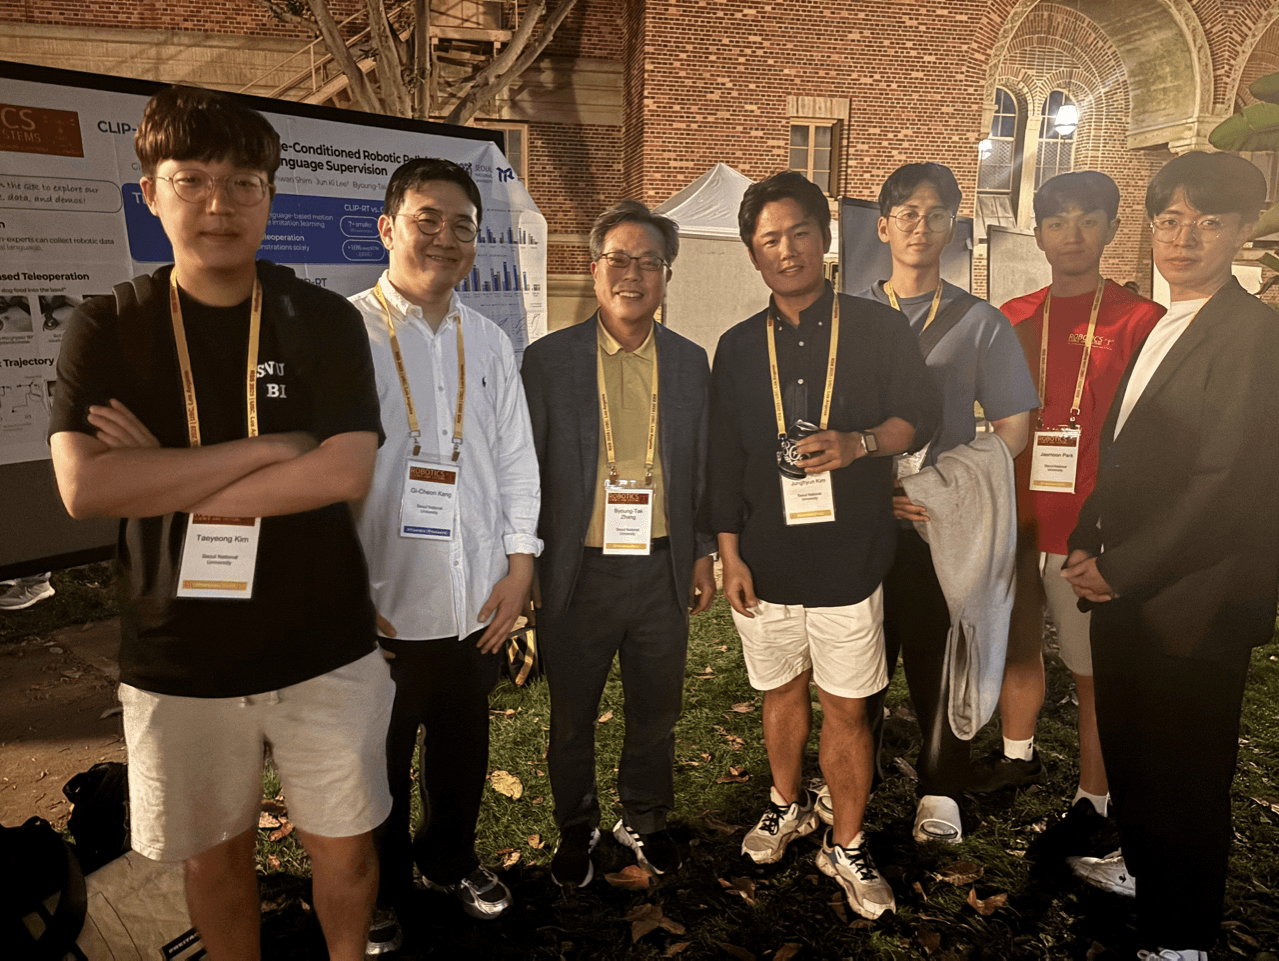
Tommoro Robotics presented CLIP-RT, a Vision-Language-Action robot foundation model developed jointly with Seoul National University, at Robotics: Science and Systems (RSS) 2025. The model is designed to let robots learn manipulation skills through natural-language instructions such as “move the cup to the shelf,” without specialized teaching setups such as teleoperation.
Built on a contrastive imitation learning framework, CLIP-RT jointly learns from visual, language, and action information to map visual observations and verbal instructions to robot actions. With approximately one billion parameters, the relatively lightweight model achieved an average task-success rate about 24 percentage points higher than Stanford’s seven-billion-parameter OpenVLA in the reported evaluation.
CLIP-RT achieved a 92.8% task-success rate on the LIBERO robot-manipulation benchmark and a real-time control rate of up to 163 Hz. It also demonstrated the ability to generalize to new tasks from a small number of demonstrations, indicating potential for industrial use.
The research is a collaboration between Tommoro Robotics and Seoul National University’s AI Institute, led by Professor Byoung-Tak Zhang, the institute’s director. By directly connecting natural language with robot control, the work helps simplify robot teaching to the level of spoken instructions.